
Loss Functions for Ordinal Regression
Ordinal regression has order structure between classes and there are dedicated loss functions to use this information.
11 posts
Ordinal regression has order structure between classes and there are dedicated loss functions to use this information.
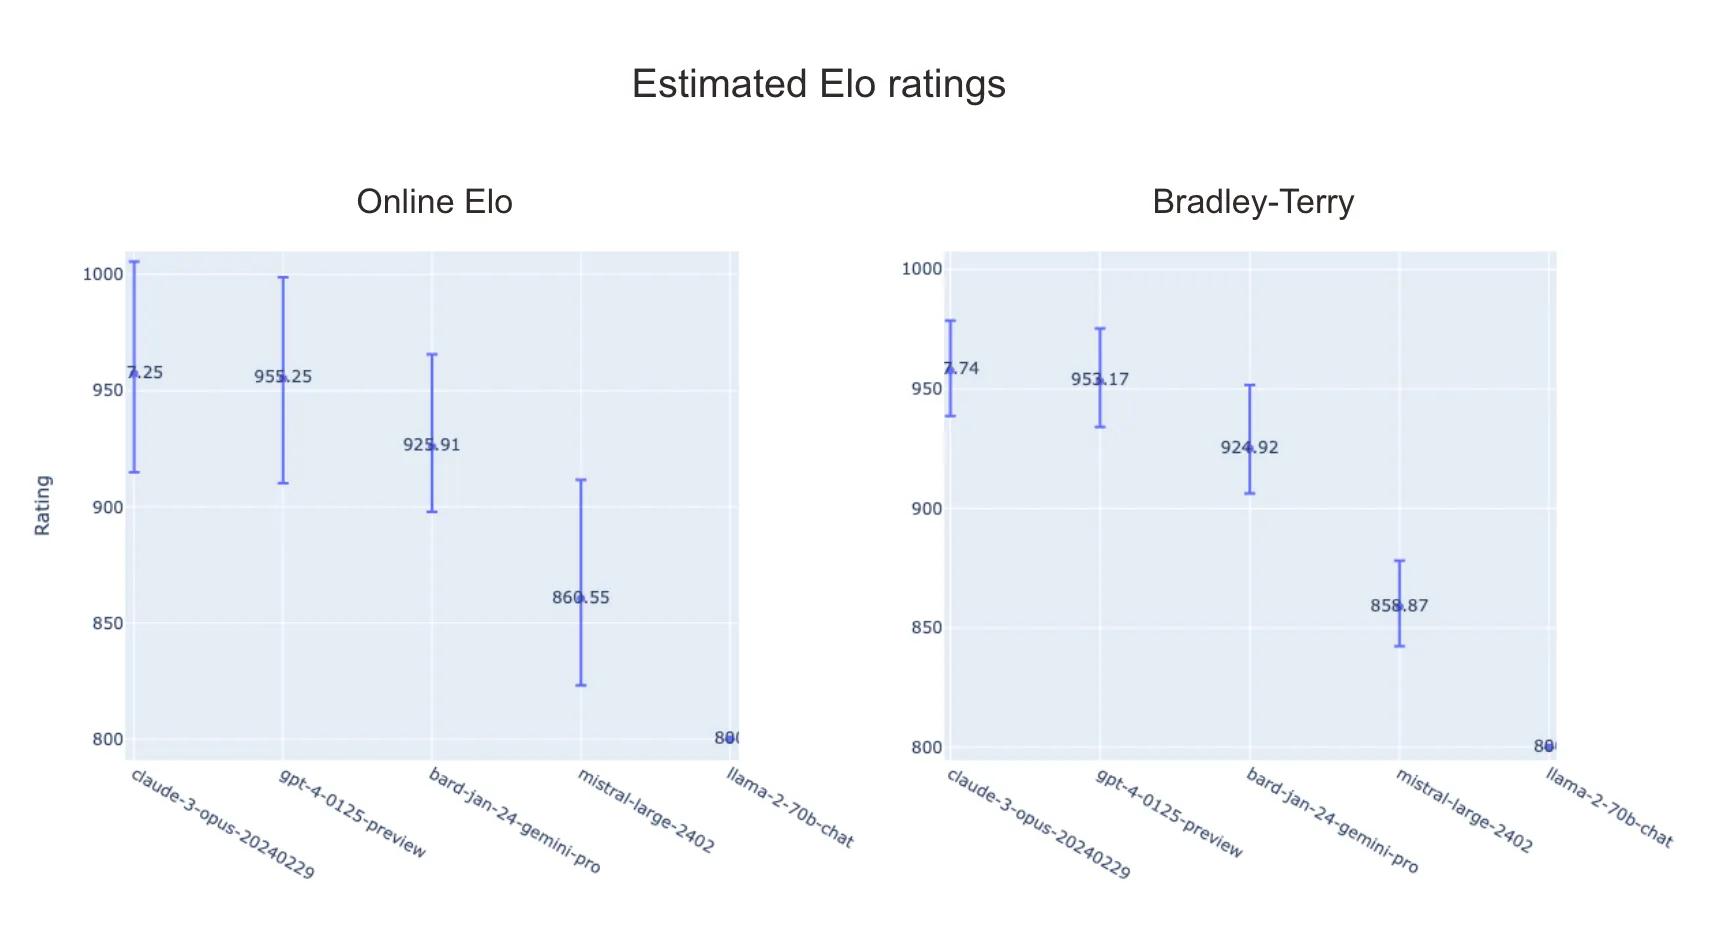
Chatbot Arena updated its LLM ranking method from Elo to Bradley-Terry. What changed? Let's dig into the differences.
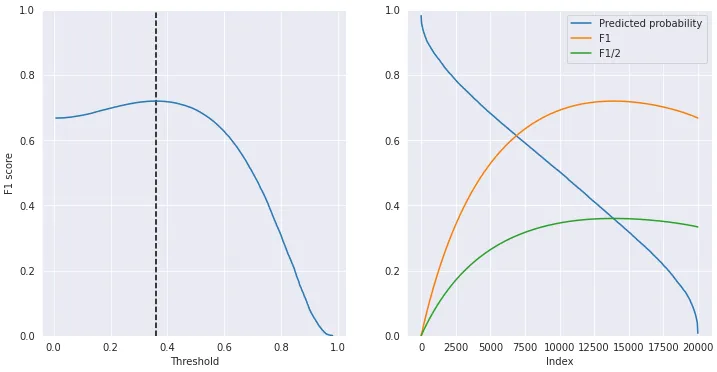
This post attempts to take a deeper look at F1 score. Do you know that, for calibrated classifiers, the optimal threshold is half the max F1? How come? Here it's explained.

This post steps forward to multiple linear regression. The method of least squares is revisited --with linear algebra.

This post summarizes the basics of simple linear regression --method of least squares and coefficient of determination.
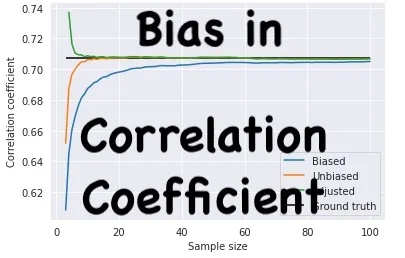
Is the sample correlation coefficient an unbiased estimator? No! This post visualizes how large its bias is and shows how to fix it.

The correlation coefficient is a familiar statistic, but there are several variations whose differences should be noted. This post recaps the definitions of these common measures.
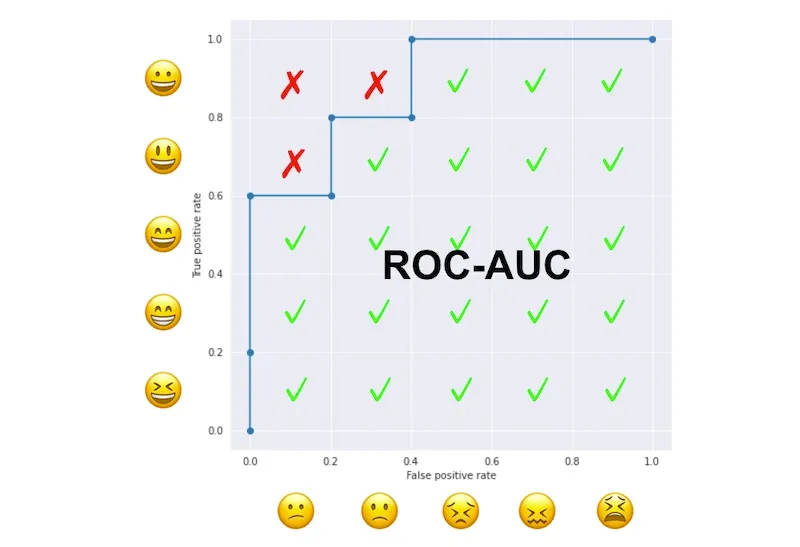
How come ROC-AUC is equal to the probability of a positive sample ranked higher than negative ones? This post provides an answer with a fun example.
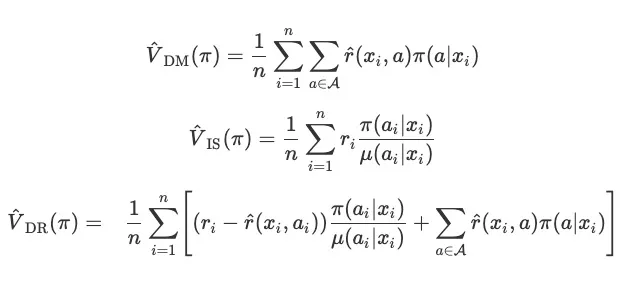
Causal inference is becoming a hot topic in ML community. This post formulates one of its important concepts called doubly robust estimator with simple notations.
『統計のための行列代数』のまとめと感想です.末尾に誤植と思われる箇所を挙げています.
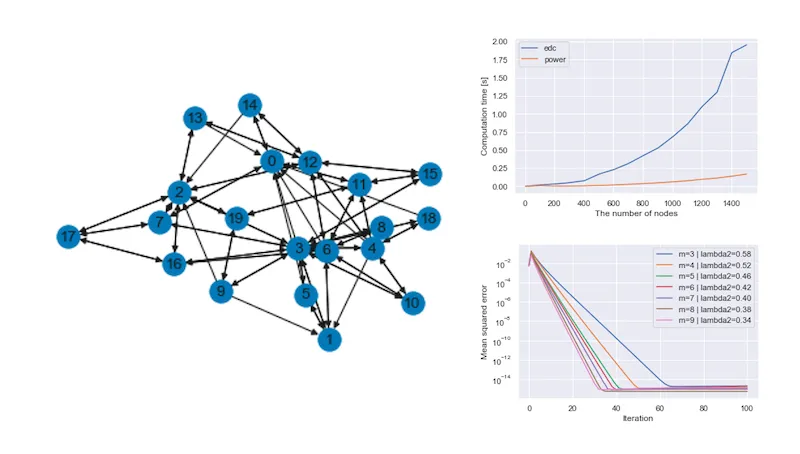
How does Google's PageRank work? Its theory and algorithm are explained, followed by numerical experiments.